Why Current AI Video Generation Technology Still Struggles to Match Reality
- Physics Failures: Models lack an understanding of gravity, cause-and-effect, and 3D spatial geometry.
- Temporal Inconsistency: Characters and environments often warp or change appearance mid-clip.
- Control Gaps: There is currently no way to provide granular directorial instructions (e.g., "move the hand two inches left").
The arrival of high-profile models like OpenAI’s Sora and its successors created a "Sora Effect"—a widespread belief that professional-grade cinematography is now just a text prompt away. However, for those working in production houses and marketing agencies, the gap between these curated viral demos and the tools available for daily use remains significant. While AI video is notably innovative, it currently functions more like a high-speed hallucination than a reliable camera.
The fundamental issue lies in how these models are built. They are trained to predict the next most likely pixel in a sequence based on massive datasets of existing footage. They do not "understand" that a glass is a solid object or that a person has a skeletal structure. This lack of a "world model" leads to the surreal glitches that define the current state of the technology. To use these tools effectively, professionals must treat them as a starting point in a much larger, human-led workflow.
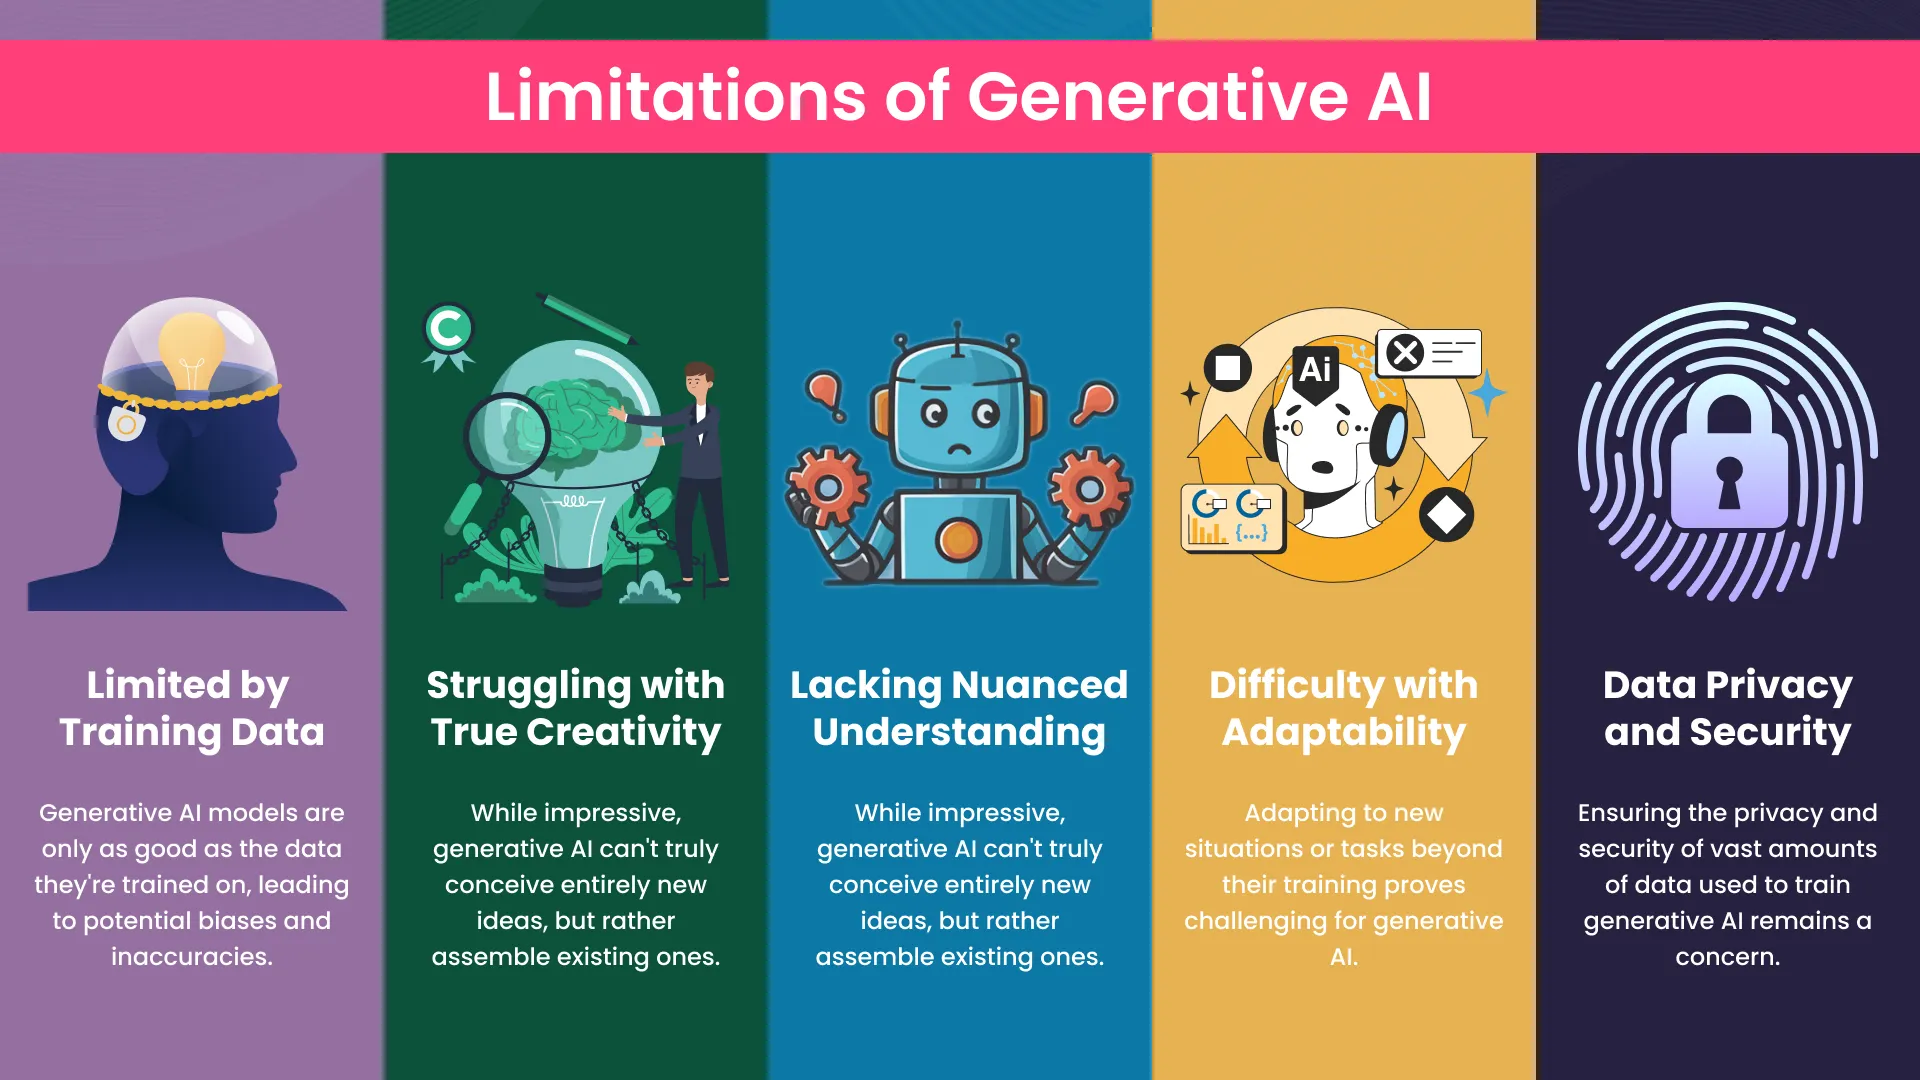
Image source: Brilworks
Why AI Models Fail to Understand Basic Physics and Space
One of the most jarring limitations of current AI video generation technology is its frequent disregard for the laws of physics. Because the AI is predicting light patterns rather than plotting 3D geometry, it has no concept of "object permanence" or spatial boundaries. This leads to several common pitfalls that can ruin a professional render in seconds.
The Problem With Objects Passing Through Solid Walls
In a traditional 3D render, software like Blender or Unreal Engine uses "collision detection" to ensure objects don't overlap. AI has no such constraint. It is common to see a car drive through a brick wall as if it were a ghost, or a person’s arm merge into a table. According to expert analysis from TechXplore, this happens because the AI is simply trying to satisfy the visual "vibe" of the prompt without calculating the underlying physical space. If the model thinks a car and a wall both belong in the frame, it may blend them together if the training data didn't explicitly show the consequences of a collision.
Why Gravity and Cause-and-Effect Often Break Down
The "burger bite" paradox is a classic example of AI's lack of cause-and-effect. A user might prompt a video of a person taking a bite of a sandwich. In the resulting clip, the person brings the sandwich to their mouth, chews, and pulls the sandwich away—but the sandwich remains perfectly whole. The AI understands the *action* of eating but fails to understand that the action must result in a physical change to the object. Similarly, you may see glass shards float upward after a bottle breaks, or liquid flow uphill, because the model hasn't "learned" gravity as a constant rule, only as a common visual pattern.
The Challenge of Rendering Realistic Human Anatomy and Fine Details
While AI has improved at rendering faces, it still struggles with the "six-finger" problem in motion. Human extremities—fingers, toes, and limbs—are complex to track across frames. As a hand moves, the AI often loses track of which finger is which, leading to digits that merge, disappear, or multiply. This extends to fine details like logos and text. If a character is wearing a shirt with a specific brand logo, that logo will often warp into an unreadable smudge the moment the character turns or the lighting changes. This makes AI video a difficult choice for brand-specific advertising where visual accuracy is non-negotiable.
The Struggle to Maintain Temporal Consistency Across Scenes
Temporal consistency refers to the ability of a video to keep its elements stable over time. In professional filmmaking, a character's shirt doesn't change from blue to green between shots. In AI video, this is a constant battle.
Why Characters Change Appearance Between Frames
The "spatiotemporal consistency" bottleneck is perhaps the biggest hurdle for narrative storytelling. Because the AI generates video in small chunks or "latents," it often "forgets" what happened a few frames prior. A character might start a scene with long hair and end it with a bob, or their eye color might shift mid-sentence. For a 30-second commercial, these micro-shifts create an "uncanny valley" effect that distracts the viewer and undermines the brand's credibility. Maintaining a consistent "seed" or character reference is a top-tier challenge that current tools have yet to solve fully.
The Challenge of Keeping Backgrounds Stable During Camera Movement
When a real camera pans across a room, the furniture stays in the same place. When an AI "camera" pans, the model often hallucinates new details to fill the space. This results in "warping" environments where a window might slide across a wall or a chair might transform into a lamp as it enters the frame. This lack of background stability makes it nearly impossible to use AI for complex tracking shots or scenes requiring precise set design. As noted by Crews Control, traditional editing still holds a significant advantage here because it relies on captured reality rather than predicted pixels.
Image source: Vegavid Technology
Current Production Constraints That Limit Professional Use
Beyond the visual glitches, there are practical, operational limits that prevent AI from replacing traditional film crews. These constraints are often omitted from marketing materials but are immediately apparent to anyone trying to produce a full-length video.
Why Most AI Generators Are Stuck With Short Clip Durations
As of 2026, the industry standard for high-quality raw AI generation is between 3 and 15 seconds. While some models claim to produce minutes of footage, the visual fidelity almost always degrades exponentially after the first few seconds. The compute cost required to maintain high-resolution consistency over a long duration is currently too high for most consumer or even enterprise-level servers. This forces creators to generate dozens of short clips and "stitch" them together, which introduces even more consistency issues.
The Silent Film Problem and the Need for Manual Sound Design
Most AI video generators are essentially "silent film" creators. While there are emerging tools for AI audio, syncing them with the generated video is a distinct research challenge. A video of a glass breaking is far less impactful if the "crash" sound happens half a second too late or sounds like a muffled thud. Multimodal alignment—the ability for an AI to understand that a specific visual movement must produce a specific sound at a specific millisecond—is still in its infancy. This means professionals must still employ foley artists or use separate AI sound tools to make the footage usable.
The Directorial Intent Gap and the Lack of Granular Control
In traditional cinematography, a director can tell an actor to "tilt your head slightly more to the left" or tell a lighting tech to "dim the key light by 20%." AI operates like a "black box" or a slot machine. You provide a prompt, and you get what the AI gives you. If the actor's expression is perfect but their hat is the wrong color, you often have to re-roll the entire prompt, losing the perfect expression in the process. This lack of granular, "knob-turning" control is why AI is currently a top choice for inspiration and storyboarding but a difficult tool for final, high-stakes production.
Comparing AI Video vs. Traditional Cinematography
| Feature | AI Video (Current State) | Traditional Cinematography |
|---|---|---|
| Physics Accuracy | Low; prone to morphing and gravity fails. | Perfect; follows natural laws. |
| Directorial Control | Limited to text prompts and "seeds." | Granular; frame-by-frame precision. |
| Consistency | High risk of character/environment warping. | Absolute; assets remain physically stable. |
| Production Speed | Extremely fast for short clips. | Slow; requires setup, lighting, and acting. |
| Sound Integration | Usually silent; requires manual foley. | Captured in-camera or synced in post. |
Legal and Ethical Hurdles Facing Commercial AI Video
Even if the technology were perfect, the legal landscape surrounding AI video is a minefield. For businesses, the risk of a lawsuit often outweighs the benefits of faster production.
Navigating the Copyright Minefield of Scraped Training Data
AI models are trained on millions of hours of footage, much of which was scraped from the internet without the explicit consent of the original creators. In the United States, courts are still debating whether this constitutes "fair use." For a brand, using a video generated by a model that might be ruled illegal in twelve months is a massive liability. Many enterprise-level companies are waiting for "indemnified" models—tools where the provider takes legal responsibility for the training data—before they fully commit to the technology.
Protecting Likeness Rights for Real People and Celebrities
There is a notable "Celeb Data Bias" in current models. Because there is so much footage of famous actors and politicians online, AI is exceptionally strong at faking their likenesses. However, it is much worse at generating a consistent, generic "CEO" for a corporate training video. This creates two problems: 1. The risk of accidentally generating a "deepfake" that infringes on a celebrity's right of publicity. 2. The difficulty of creating a unique, branded character that doesn't look like a distorted version of someone famous.
"The legal risk isn't just about the training data; it's about the output. If your AI-generated mascot looks 5% too much like a Disney character, you're entering a world of legal pain that no amount of saved production time can justify."
How to Overcome These Limitations With a Hybrid Workflow
Since AI video cannot yet stand on its own for professional work, the most successful creators use a "Hybrid Workflow." This strategy treats AI as one tool in a larger belt rather than a replacement for the entire workshop.
Using AI for Storyboarding and Rough Adjustments
Instead of trying to generate the final commercial, many directors use AI to create "moving storyboards" or animatics. This allows them to visualize the pacing and composition of a scene before spending thousands of dollars on a real shoot. As suggested by RoboNeo, using AI for transcription and conceptual visualization is currently its most reliable application.
A Professional AI Video Checklist
- Verify Physics: Check every frame for "ghosting" or objects passing through each other.
- Limit Clip Length: Keep raw generations under 5 seconds to maintain maximum detail.
- Use Seed Locking: Utilize "seed" numbers to keep character features as consistent as possible.
- Manual Sound Design: Plan for a separate phase to add foley, ambient noise, and music.
- Color Grade Post-AI: Use traditional tools (DaVinci Resolve, etc.) to unify the look of different AI clips.
Essential Tools to Fix the Silent AI Problem
To make AI video usable, you must bridge the audio gap. Tools like ElevenLabs for voiceovers and specialized AI foley generators can help, but the "human touch" in an NLE (Non-Linear Editor) like Adobe Premiere or Final Cut Pro remains essential. By layering traditional sound effects over AI visuals, you can mask many of the visual "uncanny valley" issues, as the human brain is often more forgiving of visual glitches if the audio is immersive and realistic.
The Environmental and Compute Costs of Scaling AI Video
Finally, we must consider the "hidden" cost of this technology. Generating video is exponentially more resource-intensive than generating text or images. A single 10-second high-definition clip can require the same amount of electricity as charging a smartphone dozens of times. For companies looking to scale their content production, the server costs and environmental impact are significant factors.
- GPU Latency
- The time it takes for a graphics card to process a frame. High-quality video often requires "non-real-time" rendering, meaning a 10-second clip might take 10 minutes to generate.
- Compute Water Usage
- Data centers require thousands of gallons of water to cool the server racks used for heavy AI processing tasks like video diffusion.
- Inference Cost
- The actual dollar amount charged by API providers to generate a single clip, which remains significantly higher than text-based AI queries.
Frequently Asked Questions
Why does AI video struggle with human hands and movement?
AI video models operate on pixel prediction rather than anatomical knowledge. Because hands are highly articulated and move in complex ways, the AI often loses track of individual fingers across frames. It doesn't "know" a hand has five fingers; it only knows that a certain cluster of flesh-colored pixels usually appears at the end of an arm. When that cluster moves, the prediction often fails, leading to warping or extra digits.
Can AI-generated video be used for commercial purposes legally?
The legality is currently a "gray area" in the US. While you can use it, you may not be able to copyright the output, meaning competitors could potentially use your AI-generated assets without permission. Furthermore, if the model was trained on copyrighted material without a license, your brand could face secondary infringement risks. Most experts recommend using "indemnified" tools for high-stakes commercial work.
How do you maintain character consistency in AI video?
Currently, the most effective way is through "seed" management and "LoRA" (Low-Rank Adaptation) training. By using a consistent mathematical starting point (the seed) and training a small sub-model on a specific character's face, you can improve consistency. However, even with these techniques, some manual "inpainting" or traditional editing is usually required to fix mid-clip shifts.
What is the maximum length of a high-quality AI-generated video?
While some research models can generate longer sequences, the practical limit for high-fidelity, professional-grade output is 3 to 15 seconds. Beyond this point, the "temporal drift" becomes too great, and the character or environment will likely begin to warp or change significantly. Most professional AI videos are actually montages of many very short clips.
Will AI video generation eventually replace traditional cinematography?
Experts predict a 12-to-24-month horizon before AI video reaches a level of consistency suitable for complex business use. However, it is unlikely to "replace" cinematography entirely. Instead, it will likely follow the path of CGI: a powerful tool that works best when combined with real-world directing, acting, and lighting to ground the "predicted" pixels in reality.
Key Takeaways
While AI video generation technology is a top-tier tool for creative exploration, it is not yet a "one-click" replacement for professional production. Here is what you need to remember:
- Physics is the primary blocker: AI lacks a world model, leading to frequent breaks in gravity and object permanence.
- Temporal consistency is fragile: Characters and backgrounds often warp in clips longer than 10 seconds.
- Directorial control is missing: You cannot yet "direct" an AI with the precision required for high-end narrative work.
- Legal risks remain high: Copyright and likeness rights for training data are still being litigated in US courts.
- Hybrid workflows are essential: The most effective use of AI today is in combination with traditional editing, foley, and color grading.
- Compute costs are significant: High-quality video generation requires massive energy and GPU resources.
To get the most out of this technology today, focus on using AI for short B-roll, conceptual storyboarding, and visual inspiration rather than attempting to generate a full-length narrative in a single prompt.